Tag Archives: text to speech

PDFgear Launches TextaVoice, a Truly Free Text-to-Speech Solution Challenging Expensive TTS Apps

LOS ANGELES, Calif., Feb. 2, 2026 (SEND2PRESS NEWSWIRE) — PDFgear announces the launch of TextaVoice (TextaVoice.com), a completely free text-to-speech tool that turns text into natural-sounding audio in seconds. It provides online text to speech services with no sign-up, no ads, and no usage limits.
PDFgear Launches TextaVoice, a Truly Free Text-to-Speech Challenging Expensive TTS Apps
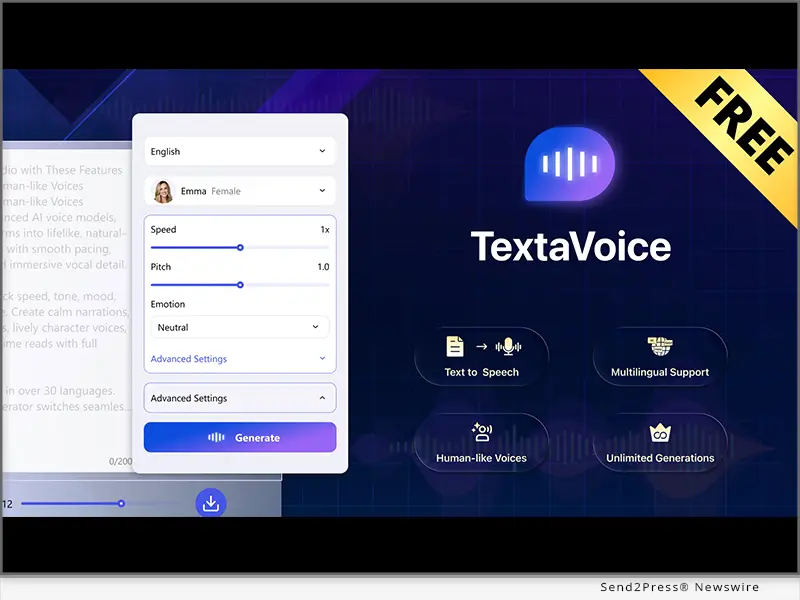
Image caption: PDFgear Launches TextaVoice,.

Many text-to-speech tools advertise free tiers, but they often come with tight limits such as character caps, conversion credits, and fewer voice options. Some also require sign-up before users can fully try the product. These barriers slow down people who simply want to generate audio and move on.

TextaVoice challenges that approach by removing the usual restrictions, allowing users to convert right away and download the audio with no strings attached. Users can generate lifelike audio from text with up to 2,000 characters per conversion.

WHO MADE TEXTAVOICE

TextaVoice is built by the team behind PDFgear, a widely recognized free alternative to Adobe Acrobat. Trusted by millions, PDFgear products are known for being powerful, easy to use, and genuinely free.

TextaVoice carries that same product philosophy into text-to-speech. In the same way PDFgear’s online tools became a reliable solution for PDF tasks, it aims to offer a simple, frictionless text-to-speech experience users can rely on.

WHAT MAKES TEXTAVOICE DIFFERENT

Free and unlimited: No subscriptions, credits, or usage limits

Human-like voice quality: Natural speech with smooth pacing powered by Advanced AI Model

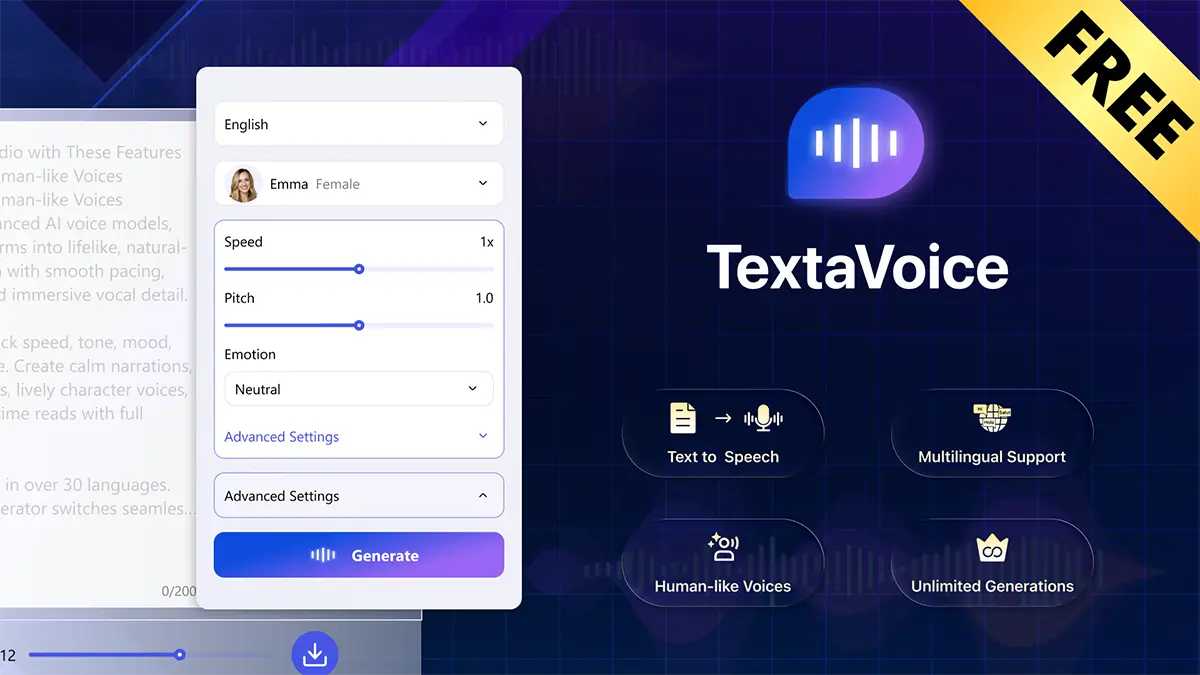
Voice controls: Adjustable speed, pitch, and emotion

30+ languages and 236 styles: Multilingual output with a wide range of voice characters

Fast MP3 export: Ready for videos, podcasts, training, and social clips

Commercial use allowed: Royalty-free audio with no attribution required

“TextaVoice is designed to deliver clearer, more natural, and more expressive speech,” said a TextaVoice spokesperson. “It uses neural voice models with prosody modeling to control timing, emphasis, and intonation for more lifelike delivery. This is our initial release, and we plan to keep improving it over time. We’re making it free so more people can try it, share feedback, and help shape the product.”

AVAILABILITY

TextaVoice is available now at https://www.TextaVoice.com/. Users can paste text, select a voice and language, and generate instantly downloadable audio.

ABOUT TEXTAVOICE & PDFGEAR

TextaVoice is developed by the PDFgear team, creators of an AI-powered PDF suite trusted by millions for being free, powerful, and user-first. TextaVoice brings the same user benefit first approach to AI voice. Powered by advanced neural voice models, it turns text into clear, natural-sounding audio across multiple languages and voice options.

Learn more: https://www.TextaVoice.com/

MEDIA CONTACT:

blair_zhou@pdfgear.com

MULTIMEDIA:

Image link for media: https://www.Send2Press.com/300dpi/26-0202-s2p-textavoice-300dpi.webp

Image Caption: PDFgear Launches TextaVoice.

NEWS SOURCE: PDFgear


This press release was issued on behalf of the news source (PDFgear), who is solely responsible for its accuracy, by Send2Press Newswire. Image, if any, was provided by the news source and not this website or the wire service. Information is believed accurate, as provided by the news source, but is not guaranteed.

To view the original story, visit: https://www.send2press.com/wire/pdfgear-launches-textavoice-a-truly-free-text-to-speech-solution-challenging-expensive-tts-apps/

Copr. © 2026 Send2Press® Newswire, Calif., USA. -- REF: S2P STORY ID: S2P132693 NOREL-3B


FineVoice Announces V3.0: Elevating AI Voice Generation with Expressive and Personalized Voice Creation

FineVoice Launches 3.0 Update: Introducing More Expressive and Customizable AI Voices

LOS ANGELES, Calif., Jan. 29, 2026 (SEND2PRESS NEWSWIRE) — FineVoice, a leading AI voice generation platform, today officially announced the launch of FineVoice 3.0. Moving beyond standard functional iterations, this major upgrade delivers comprehensive enhancements in vocal expressiveness, emotional nuance, and creative flexibility. With FineVoice 3.0, users benefit from refined customization of tone, pacing, and delivery, empowering users to synthesize professional audio that resonates with the specific stylistic demands of all-encompassing content types.

The Most Diverse and Expressive AI Voice Generator
Image caption: The Most Diverse and Expressive AI Voice Generator.

FineVoice 3.0 introduces richer, more expressive AI voices along with a suite of new capabilities. With FineVoice, users can instantly generate high-quality, royalty-free, and lifelike voiceovers, sound effects, and background music. The platform also allows flexible transformation or enhancement of vocal style and enables rapid conversion of articles, scripts, PDFs, and other content into podcast-style audio, substantially reducing both the time and technical expertise typically required for professional audio production.

Traditionally, achieving high-caliber audio has been gated by specialized hardware and labor-intensive post-production, creating a bottleneck for rapid iteration and large-scale distribution. FineVoice 3.0 addresses these challenges by making voice creation more intuitive and efficient, while offering the flexibility to adapt seamlessly to diverse content types and production scenarios.

“FineVoice 3.0 is not a routine update, but a release designed to help creators produce audio content that is ready for immediate publication—faster, more consistently, and with professional-grade quality,” said Manager of FineVoice. “Using simple text input, users can create emotionally resonant, production-ready audio with stylistic consistency. By integrating voice, sound effects, and music within a single platform, FineVoice 3.0 allows creators to perform more audio tasks efficiently, accelerating the process from initial spark to final production. ”

FineVoice 3.0 is now officially available. To explore the full potential of these new features, please visit: https://finevoice.ai.

ABOUT FINEVOICE

FineVoice is a versatile AI voice creation platform that helps users create high-quality, personalized audio efficiently. It converts written content into natural, expressive voiceovers, sound effects, and music. FineVoice supports 154 languages and serves a wide spectrum of professional applications, including article narration, podcast production, video voiceovers, and educational audio content.

To better support long-term product development, brand independence, and the continuous optimization of user experience, FineVoice has recently transitioned to independent operation, separating from Fineshare, and has officially migrated its website from finevoice.fineshare.com to https://finevoice.ai.

Moving forward, FineVoice will continue to focus on creators’ needs and expand the role of AI voice in content creation and distribution.

NEWS SOURCE: FineVoice


This press release was issued on behalf of the news source (FineVoice), who is solely responsible for its accuracy, by Send2Press Newswire. Image, if any, was provided by the news source and not this website or the wire service. Information is believed accurate, as provided by the news source, but is not guaranteed.

To view the original story, visit: https://www.send2press.com/wire/finevoice-announces-v3-0-elevating-ai-voice-generation-with-expressive-and-personalized-voice-creation/

Copr. © 2026 Send2Press® Newswire, Calif., USA. -- REF: S2P STORY ID: S2P132614 NOREL-3B


BlipCut Releases Free AI Voice Generator to Create Realistic Commercial Voices

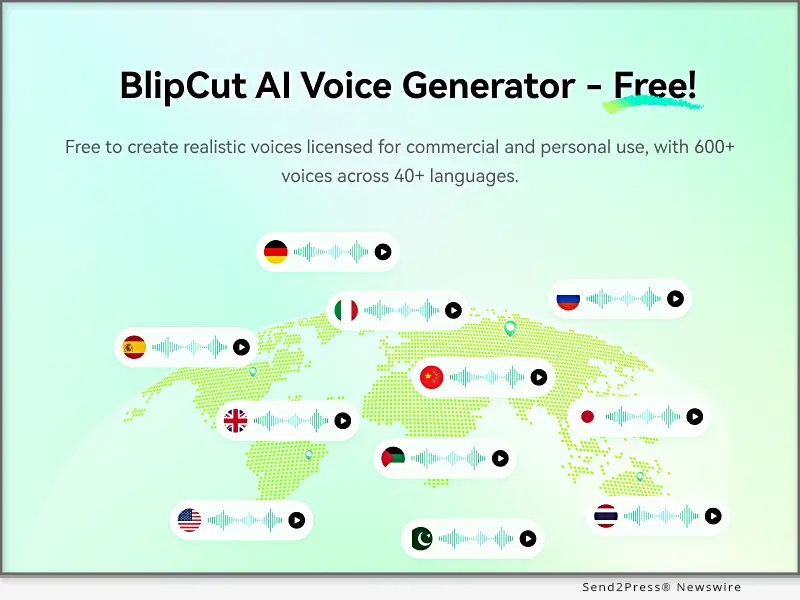
NEW YORK and HONG KONG, Nov. 11, 2025 (SEND2PRESS NEWSWIRE) — BlipCut, a rising brand in AI-driven media creation, today announced the release of BlipCut AI Voice Generator, designed to help creators, brands, and businesses instantly turn text into high-quality and natural-sounding voiceovers. This new feature brings fast, multilingual, and commercially usable voice generation to everyone, ideal for audiobooks, podcasts, e-learning, and global marketing campaigns.

BlipCut AI Voice Generator
Image caption: BlipCut AI Voice Generator.

FEATURE HIGHLIGHTS

  1. 600+ Realistic AI Voices: Choose from a wide range of natural human voices and creative tones, including conversational, narrative, commercial, character, robotic, horror, and ASMR styles.
  2. Supports 40+ Languages and Accents: Convert text to speech and generate authentic voices in major global languages such as English, Spanish, French, German, Portuguese, Russian, Japanese, and Korean, as well as regional ones like Hindi, Tamil, Urdu, Turkish, Filipino, and Mandarin Chinese.
  3. Long-Form Audio Generation: Easily convert long scripts, blog posts, or documents into full-length narrations. Perfect for audiobooks, podcasts, online courses, and voice-based storytelling.
  4. Emotion and Style Control: Go beyond basic TTS. Adjust tone, speed, and emotional delivery — calm, excited, dramatic, angry, or playful — to match your project’s mood.
  5. Commercial Use Allowed: All generated voices can be used for commercial purposes, making it ideal for brands, marketers, and production studios.

WHY CHOOSE BLIPCUT AI VOICE GENERATOR?

Traditional voice recording is time-consuming, expensive, and requires professional equipment or voice actors. BlipCut’s AI Voice Generator eliminates these barriers, delivering:

  • Instant Delivery – Generate voiceovers in seconds with simple text input.
  • Cost Efficiency – No need for studio sessions or external voice talent.
  • Global Reach – Speak to audiences in 40+ languages effortlessly.
  • Consistent Brand Voice – Maintain a cohesive, on-brand tone across multilingual content.

ABOUT BLIPCUT

BlipCut is an AI-powered multimedia creation platform that enables users to translate videos in over 140 languages. With the launch of its AI Voice Generator, BlipCut expands its mission to make professional-quality voice creation accessible to everyone.

To know more, you may visit: https://www.blipcut.com/

Our Social Media:

YouTube: https://www.youtube.com/@BlipCut_Online

X/Twitter: https://x.com/BlipCutofficial

Facebook: https://www.facebook.com/blipcut

Linkedin: https://www.linkedin.com/company/blipcutvideotranslator

Discord: https://discord.gg/vk4Z2YWGsG

NEWS SOURCE: BlipCut


This press release was issued on behalf of the news source (BlipCut), who is solely responsible for its accuracy, by Send2Press Newswire. Image, if any, was provided by the news source and not this website or the wire service. Information is believed accurate, as provided by the news source, but is not guaranteed.

To view the original story, visit: https://www.send2press.com/wire/blipcut-releases-free-ai-voice-generator-to-create-realistic-commercial-voices/

Copr. © 2025 Send2Press® Newswire, Calif., USA. -- REF: S2P STORY ID: S2P130936 NOREL-3B


iMyFone VoxBox TTS Voice AI Launches Video Dubbing Feature

NEW YORK, N.Y. /ScoopCloud/ -- iMyFone VoxBox, a leading text to speech voice generator in voice AI technology, is thrilled to announce the launch of its highly anticipated video dubbing feature. This new addition empowers users to effortlessly add high-quality voiceovers to their videos, revolutionizing the way content is created and consumed.

With the new video dubbing feature, VoxBox AI Voice Generator aims to simplify the process of adding text to speech voiceovers to video content. Whether you're a content creator, marketer, educator, or business professional, VoxBox provides the tools you need to enhance your videos with professional-grade audio.

Co-founder of iMyFone, James says: "VOXBOX introduces its new video dubbing feature to enhance content creation with seamless, high-quality human and anime text to speech. Driven by our vision to simplify video production, this feature empowers users to effortlessly integrate professional-grade audio, making it easier to connect with global audiences and elevate content to new heights."

:: VoxBox AI Voice Generator Full Features:

Realistic text to speech: Offering more than 3500 AI voices, from narrations and tutorials to advertisements and entertainment, VoxBox delivers crystal-clear audio that elevates your production quality.

Advanced voice cloning: Customize your voice within seconds by using its advanced AI voice cloning technology. It allows you to replicate specific voices to create unique voice experiences.

Multi-Language Support: Reach a global audience with multi-language support. It enables you to add TTS in various languages to access a wider audience.

Customization Options: Various customization options, including pitch, speed, tone and emotion adjustments to ensures that your audio perfectly aligns with your video's content.

Video Dub: This feature simplifies adding professional-grade, multilingual voiceovers and personalized voice cloning to your videos.

:: Use Case for Text to Speech with iMyFone VoxBox:

1. Add realistic, dramatic or humorous AI text to audio to social media content, making content stand out.

2. Reach a global audience by dubbing videos in multiple languages with native-like accuracy.

3. Enhancing gaming experience with immersive voiceovers to game trailers and walkthroughs.

4. Bring stories to life with expressive AI voice for audiobooks and storytelling videos.

5. Provide clear dubbing for e-learning courses, PPT and PDF.

6. Text to song with AI rapper voices, let your lyrics sing!

:: 3 Steps to Create Video Dub with VoxBox Voice Maker:

1. Download and install iMyFone VoxBox and launch it.

2. Choose text to speech voice and type your text.

3. Upload your video and add TTS voiceover, then export it.

You can now try iMyFone VoxBox for free or enjoy more features less than $0.54/day!

Want to know more details? Please visit: https://filme.imyfone.com/voice-recorder/

About iMyFone:

iMyFone is a leading software company that focus on mobile data recovery, iOS system repair, location changer, voice generation, video editor and more than 50+ software. More than 3 million users from 200+ countries trusted iMyFone in past 9 years. So, iMyFone VoxBox AI voice generator will offer you the best experience!

Social Media:

X/Twitter: https://twitter.com/voicetechfilme/

YouTube: https://www.youtube.com/@iMyFoneFilmeVideoEditor/videos

Discord: https://discord.com/invite/G9hZWrGNnY

Instagram: https://www.instagram.com/iMyFoneFilme/

VIDEO (YouTube): https://youtu.be/F6u5EfGdPaA?si=gSwCsIFOXpexntt2

RELATED LINKS:

https://filme.imyfone.com/voice-recorder/ai-voice/

https://filme.imyfone.com/voice-changer/

https://filme.imyfone.com/rapper-deep-voice/

https://filme.imyfone.com/voice-cloning/

News from IMyFone

iMyFone VoxBox, a leading text to speech voice generator in voice AI technology, is thrilled to announce the launch of its highly anticipated video dubbing feature. This new addition empowers users to effortlessly add high-quality voiceovers to their videos, revolutionizing the way content is created and consumed.

Related link: https://www.imyfone.com/

This version of news story was published on ScoopCloud™ (ScoopCloud.com) - part of and © the Neotrope® News Network - all rights reserved.

Offline Text to Speech Converter: Making Digital Voices Sound Real

NEW YORK, N.Y. /ScoopCloud/ -- In a world of ever-evolving tech, EaseText is changing the speech synthesis game. EaseText Text to Speech Converter, crafted by a team of skilled engineers, makes text talk with a lifelike voice. The software offers a real voice to break barriers between text and speech. Whether you're a content creator, a teacher, or just someone who wants great-sounding speech, EaseText Text to Speech Converter must be your essential tool.

Endless Possibilities

EaseText opens doors to tons of text-to-speech powers that were once out of reach. What sets EaseText Text to Speech Converter apart is that it's excellent and affordable. It's a smart tool that makes natural sounds accessible to everyone.

A Personal Touch

EaseText Text to Speech Converter brings personalization to the forefront. With Voice Cloning, it's not just tech; it's a way to add a human touch to digital stuff. Think about having your content read by a voice that's all yours or a company having its own unique sound.

Key Features:

1 Offline Functionality

Work seamlessly without an internet connection, ensuring uninterrupted access to lifelike speech synthesis anywhere, anytime.

2 Voice Variety

Choose from a vast library of over 1300 voices, including the ability to clone and use your own voice, allowing for truly personalized audio creations.

3 Language Support

Support for 30 languages, including English, Spanish, Dutch, Italian, Chinese, Russian, Portuguese, German, and more.

4 File Format Compatibility

Effortlessly convert text from various file formats, such as TXT, Word and Excel into high-quality audio.

5 Bulk Conversion

Easily convert text in bulk from multiple files, streamlining your workflow for increased productivity.

6 Real-Time Processing

Experience real-time text-to-speech synthesis, with speedy conversions that take just minutes to transform input text into audio.

7 Voice Cloning

Utilize advanced AI-powered voice cloning to replicate and use your own voice, adding a personal touch to every audio creation.

8 Privacy Assurance

Rest easy knowing your data remains secure as the software operates entirely offline, eliminating concerns about data privacy and security.

9 Affordable Pricing

In a world where fancy tech can cost a fortune, EaseText Text to Speech Converter stands out with its Affordable Pricing. It means that the software is now in everyone's reach, from startups to schools, and folks like you.

10 User-Friendly Interface

Enjoy the user-friendly and intuitive interface. Easy for users of all levels to create professional-grade audio content. Tutorial: https://www.easetext.com/tutorial/how-to-use-offline-text-to-speech-software-on-pc.html

CEO Vincent's Vision:

Vincent, the boss at EaseText, saying, "We're just getting started. We see EaseText Text to Speech Converter becoming a must-have tool across industries, changing how we interact with tech and each other."

Price and Availability:

For personal 1 computer usage, it is available at $3.95 /month. You also can buy the Family edition that $5.95 /month for 3 computers.

Learn More: https://www.easetext.comeasetext.com/purchase-tts-converter.html

https://www.easetext.com/text-to-speech-converter.html

About EaseText:

EaseText Software is a leading software development company providing digital data management software solutions. Founded in 2012, EaseText has been an award-winning developer, especially in the image, audio, video, PDF and text converting field.

More information: https://www.easetext.com/text-to-speech-converter.html

Facebook: https://www.facebook.com/easetext

X(Twitter): https://twitter.com/ease_text

YouTube: https://www.youtube.com/@easetext

News from EaseText Software

In a world of ever-evolving tech, EaseText is changing the speech synthesis game. EaseText Text to Speech Converter, crafted by a team of skilled engineers, makes text talk with a lifelike voice. The software offers a real voice to break barriers between text and speech. Whether you're a content creator, a teacher, or just someone who wants great-sounding speech, EaseText Text to Speech Converter must be your essential tool.

Related link: https://www.easetext.com/

This version of news story was published on ScoopCloud™ (ScoopCloud.com) - part of and © the Neotrope® News Network - all rights reserved.

Launching a new way to convert subtitles to audio using text-to-speech AI voice generators, Narakeet makes it simple to tailor videos to global audiences

WOKING, U.K. /ScoopCloud/ -- Aiming to make text to speech technology available to everyone, Narakeet today unveiled a way to seamlessly convert video subtitles into audio using state-of-the-art text to speech AI. This innovative solution emerges in response to the increasing demand for video content tailored to global audiences.

By swiftly converting written subtitles into lifelike audio narration, content creators can now effortlessly bridge language barriers. A typical use case is to provide audio tracks in different languages for videos. Instead of forcing the audience to read subtitles in a local language, video producers can engage their audiences more effectively using native audio.

Until now, providing audio tracks in multiple languages was a laborious task. Even with automated voice generators, someone would need to record lots of small sound snippets and manually synchronize them to the original visuals using video editing software. Narakeet's latest offering allows companies to localize video content by automatically synchronizing AI voice output to subtitle and closed caption timestamps, saving significant time and effort.

"Working together with clients from various industries, from religious organizations wanting to reach global audiences, to large enterprises that need to offer internal training videos to their workforce in multiple languages, we have been developing and testing this solution over the last few months. It's very exciting to be able to open it to the general public," said Gojko Adzic, founder of Narakeet.

"Instead of wasting hours on aligning audio with video, this new tool makes it trivially easy to produce alternative language soundtracks. Just upload a translated subtitle file with original timestamps, choose one of our 600 realistic voice generators in 90 languages, and get a perfectly synchronized audio track in minutes."

According to a recent report by Valuates, "The global AI Voice Generator market is expected to grow from $2.4 billion in 2023 to $7.2 billion by 2029." Making text to speech technology easily accessible to mass market consumers will be a key factor for that growth.

"Realistic text to speech technology is now easily available online, but more complex usage scenarios often require programming skills and technical knowledge beyond the reach of the usual consumer," said Adzic. "We are putting all that power in the hands of regular people, who don't have the time or skills to build their own processing systems."

The Narakeet subtitle audio generator supports both commonly used standards for subtitle files, SRT and WebVTT. It is available as an online tool for individual users, and as a developer API for companies that want to automate alternative audio track recordings for hundreds or thousands of videos.

For more information on the Narakeet subtitle audio generator, see: https://www.narakeet.com/docs/how-to/convert-subtitles-to-audio.html

For company information, visit: https://www.narakeet.com/

For images and press resources, see https://www.narakeet.com/docs/press/

Related video (YouTube): https://youtu.be/R10yrn_Nwl8

RELATED LINK/CITATION:

https://reports.valuates.com/request/sample/QYRE-Auto-33Y14030/Global_AI_Voice_Generator_Market_Research_Report_2023

News from Narakeet

Aiming to make text to speech technology available to everyone, Narakeet today unveiled a way to seamlessly convert video subtitles into audio using state-of-the-art text to speech AI. This innovative solution emerges in response to the increasing demand for video content tailored to global audiences.

Related link: https://www.narakeet.com/

This version of news story was published on ScoopCloud™ (ScoopCloud.com) - part of and © the Neotrope® News Network - all rights reserved.

Launching a new text to speech integration API, Narakeet makes it possible for anyone to access realistic, natural, text to speech voices

WOKING, U.K. /ScoopCloud/ -- Text to Speech technology adoption is surging worldwide, driven by online education, businesses struggling to provide effective training to work-from-home employees, and companies adopting emerging technologies to communicate with customers. With the new integration interface, Narakeet aims to democratize access to high quality AI voices, making it possible for anyone to easily use text to speech functionality in their own applications.

The global text to speech market is expected to reach more than $7 billion over the next four years, according to Emergen Research. Based on deep neural networks and machine learning, modern text to speech processors can mimic human voice with incredible accuracy, but they can be complicated to set up and operate.

"Over the years we've accumulated one of the largest online collections of realistic text to speech voices, with everything from popular English dialects to Icelandic and Macedonian," said Gojko Adzic, founder of Narakeet, "and we've been hearing from other application developers that they would love to get the same high quality of voices but within their software."

Narakeet is a text-to-speech video maker that turns Powerpoint slides into narrated videos. Although it had a third-party developer integration option since 2020, it was optimized for large tasks and long jobs suitable for video contents. Audio projects are a lot simpler.

"Instead of a long and complicated process, the simplified streaming API helps you achieve everything you need with just a single request," said Adzic. "Anyone can now use our collection of more than 350 voices in 60 languages and develop the integration within minutes."

Recent advances in the quality of voice output as well as hardware performance are opening new use cases for automated voice communication. According to Markets and Markets Research, the "growing need for automation and convenience is increasing the adoption of text-to-speech technology in everyday applications."

Text to speech technology is already quickly being adopted in automotive and transportation industries, in healthcare, finance, education and consumer electronics industries, and many others.

For more information, check out https://www.narakeet.com/docs/automating/text-to-speech-api/

CITATIONS:

https://www.emergenresearch.com/industry-report/text-to-speech-market

https://www.marketsandmarkets.com/Market-Reports/text-to-speech-market-2434298.html

News from Narakeet

Text to Speech technology adoption is surging worldwide, driven by online education, businesses struggling to provide effective training to work-from-home employees, and companies adopting emerging technologies to communicate with customers. With the new integration interface, Narakeet aims to democratize access to high quality AI voices, making it possible for anyone to easily use text to speech functionality in their own applications.

Related link: https://www.narakeet.com/

This version of news story was published on ScoopCloud™ (ScoopCloud.com) - part of and © the Neotrope® News Network - all rights reserved.

Adding 60 Text-to-Speech Voices, Narakeet Enables Educators To Easily Create Video Lessons in Regional Dialects

WOKING, U.K. /ScoopCloud/ -- Remote and virtual learning environments are putting educators under pressure to create engaging video materials, yet few teachers have the equipment or skills to record professional audio. Adding 60 new voices, Narakeet this week enabled educators to easily create video lessons and voiceovers in 40 languages and regional dialects.

NCTQ studies found that teachers spend 45 minutes on average planning lessons. Having to record audio and edit videos puts additional pressure on already busy schedules, often requiring hours of extra work per day. Neural AI text-to-speech systems, with natural sounding voices, offer a compelling alternative to recorded audio, cutting preparation time from hours to minutes. Until recently, AI voices only represented major language variants, limiting the effectiveness of this approach. According to Statista research, accent or dialect issues are the second biggest barrier to adoption for voice technology in 2021, affecting 66% of respondents.

"Students like to hear voices that sound like them. They engage better with content in regional dialects. Using our new voices, educators can make video lessons that speak to their audience much more effectively," said Gojko Adzic, founder of Narakeet.

Narakeet is a text-to-speech video maker that turns PowerPoint slides into narrated videos. This week's update brings support for English variants including South African, Irish, Nigerian and Filipino voices; French with Swiss, Canadian and Belgian dialects; Spanish with Mexican and Puerto Rican variants and improved Brazilian Portuguese and Indian English.

"Combined with the recent addition of Swiss German and New Zealand English, Narakeet now has a rich collection of local dialects in many popular languages, and one the largest collections of neural text-to-speech generators," said Adzic. "Some of our competitors may offer a larger list of options, but they include older technology which cannot mimic human speech, and often provide the same voice with regional variants. Narakeet does not reuse voices across local variants, so each voice is unique."

According to MarketsandMarkets research, the text-to-speech market was valued at USD 2.0 billion in 2020 and is estimated to reach USD 5.0 billion by 2026, driven by the rising demand for handheld devices and increased investment in government spending on education. The COVID-19 pandemic caused a significant growth in demand for cloud-based solutions, especially important for schools as they shifted from in-person education to remote, virtual learning environments and mixed educational models.

For more information, check out https://www.narakeet.com/

MULTIMEDIA:

VIDEO (YouTube): https://youtu.be/NI1ZkammTRE

RELATED LINKS

https://www.narakeet.com/docs/powerpoint/

News from Narakeet

Remote and virtual learning environments are putting educators under pressure to create engaging video materials, yet few teachers have the equipment or skills to record professional audio. Adding 60 new voices, Narakeet this week enabled educators to easily create video lessons and voiceovers in 40 languages and regional dialects.

Related link: https://www.narakeet.com/

This version of news story was published on ScoopCloud™ (ScoopCloud.com) - part of and © the Neotrope® News Network - all rights reserved.